 samankeon.com
Blog
Notes on how LLMs work under the hood, and a hands-on series on writing GPU kernels.
 RoPE: The Phase Geometry Behind Long-Context TransformersHow rotating query and key vectors turns absolute position into relative attentionJun 6, 2026 · #llm
 From Greedy to Nucleus, How LLMs Choose the Next TokenDecoding algorithms and sampling techniques explainedDec 22, 2025 · #llm
 MatmulA tiled CUDA matmul kernel with shared-memory caching, benchmarked against Torch.Dec 1, 2025 · #kernels
 2D WorkloadsMapping images onto CUDA thread blocks: row-major memory, 2D indexing, and a grayscale conversion kernel.Nov 22, 2025 · #kernels
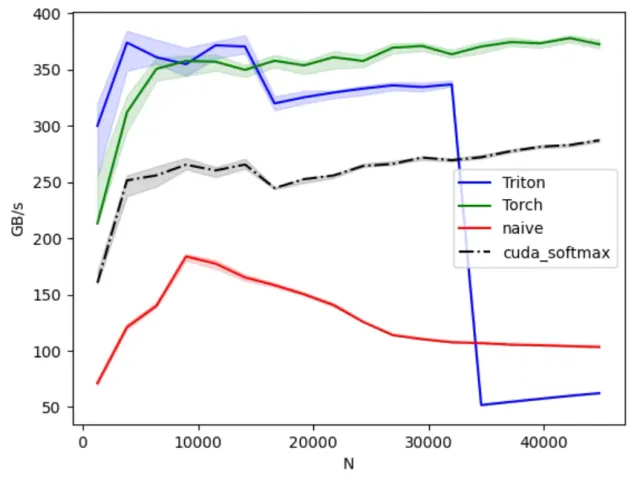 Fused Softmax::P3::Cuda KernelA CUDA softmax kernel taken from a naive per-row loop to shared memory, float4 loads, and warp-shuffle reductions.Nov 16, 2025 · #kernels
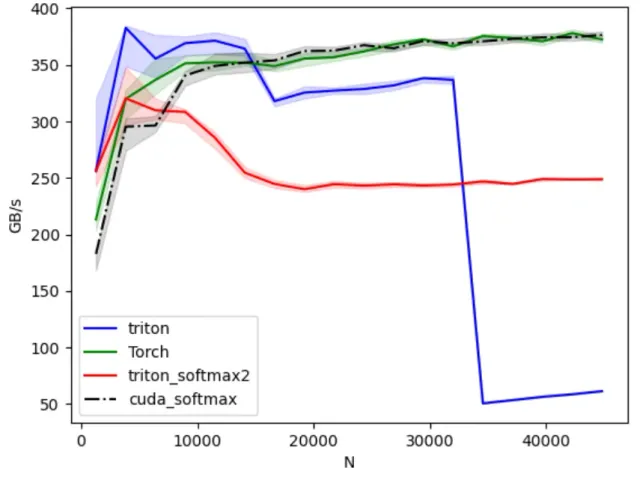 Fused Softmax::P2::Triton optimizationDebugging a Triton softmax that falls off a cliff at large row sizes, and what block size has to do with it.Nov 9, 2025 · #kernels
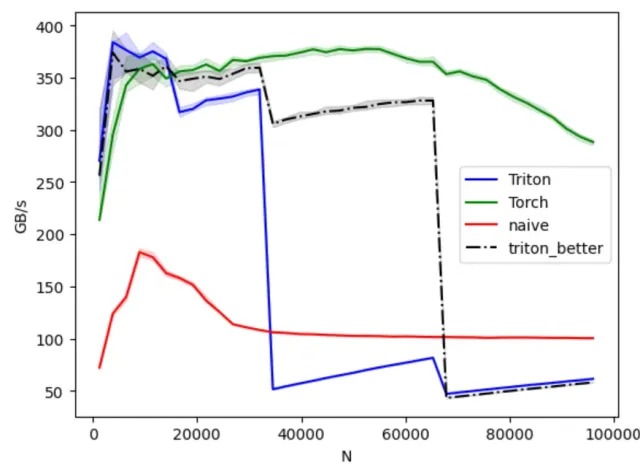 Fused Softmax::P1::Naive & Triton ImplementationSoftmax in Torch and a first Triton kernel, starting from the numerically stable formulation.Nov 2, 2025 · #kernels
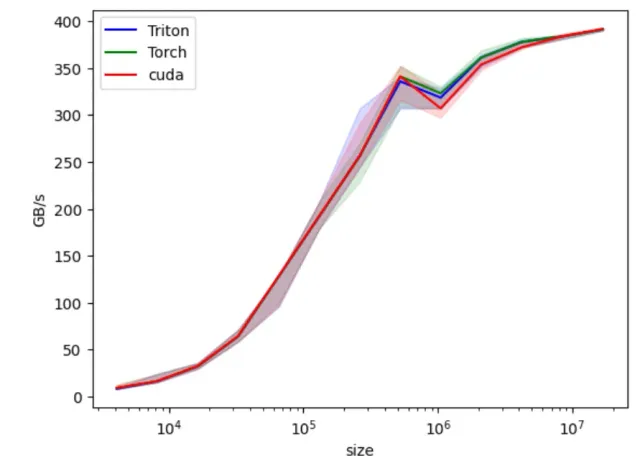 Vector Addition::P4::OptimizingVectorized memory access and a grid-stride loop bring the CUDA vector-add kernel up to Triton and Torch speed.Oct 26, 2025 · #kernels
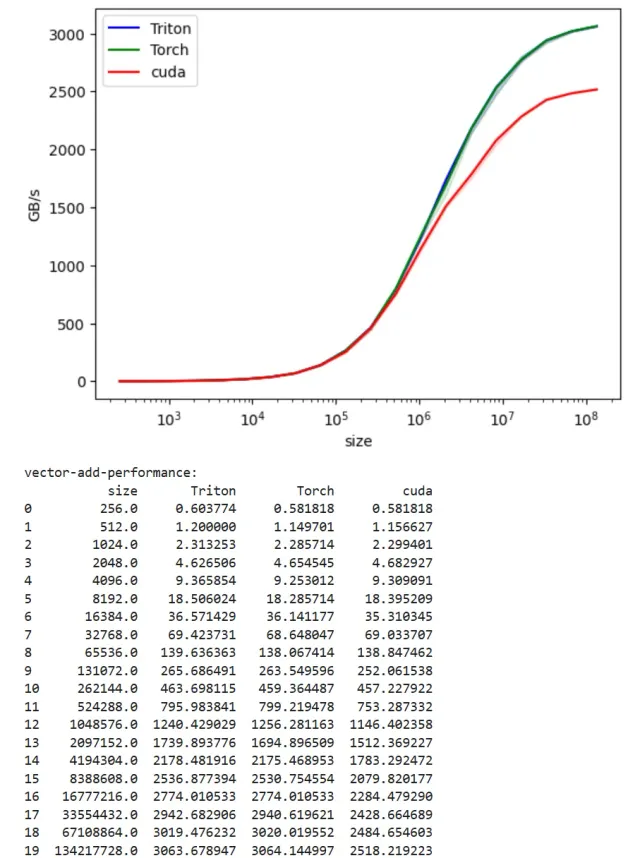 Vector Addition::P3::BenchmarkingBenchmarking the CUDA, Triton, and Torch vector-add kernels on a GTX 1080, RTX 5060, A100, and H100.Oct 12, 2025 · #kernels
- Vector Addition::P2::Cuda KernelThe same vector addition written in raw CUDA: grids, blocks, threads, and host-to-device memory transfer.Oct 5, 2025 · #kernels
- Vector Addition::P1::Triton KernelA first Triton kernel: vector addition, with pointers, blocks, and masking explained line by line.Sep 28, 2025 · #kernels
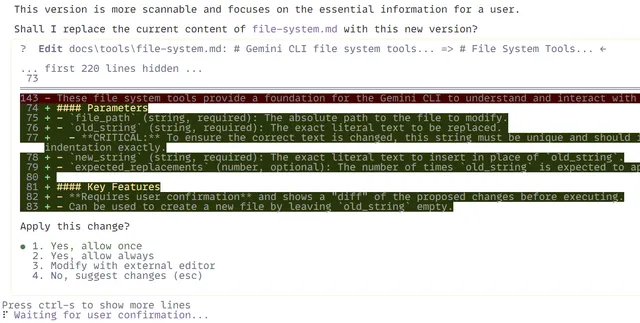 The Command Line is Learning to TalkA deep dive into Gemini CLI, Claude CLI, and the rise of shell-native AI agents.Sep 16, 2025 · #llm
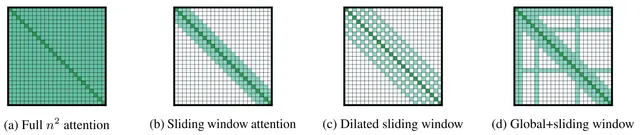 Breaking the Quadratic BarrierAn Engineer's Guide to the Attention Hacks Behind Million-Token LLMsSep 9, 2025 · #llm
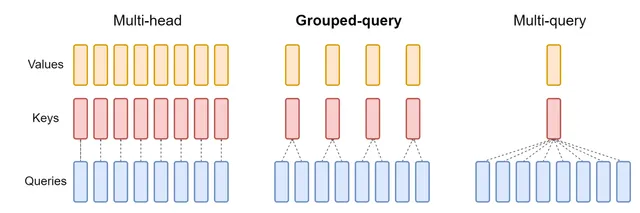 Attention Isn't All You Need. You Also Need a Memory BudgetAn Engineer's Guide to GQA and FlashAttention: The Hacks That Tamed the Transformer's Memory ProblemSep 2, 2025 · #llm
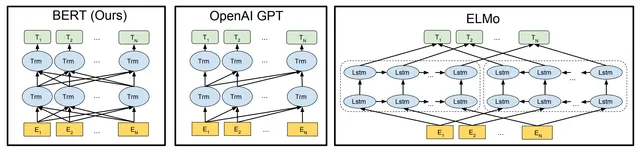 From Word2Vec to BERT: The Evolution of Language EmbeddingsHow we taught machines to understand not just words, but the meaning behind themAug 26, 2025 · #llm
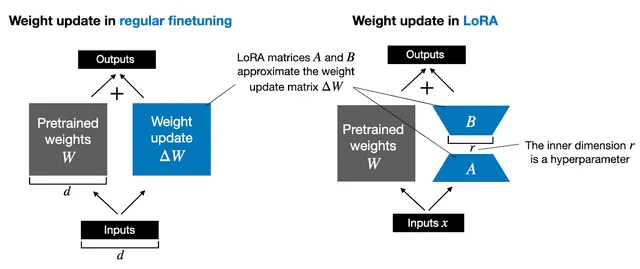 From Brute Force to Finesse: The Story of Parameter-Efficient Fine-Tuning (PEFT)How we learned to teach billion-parameter titans new tricks without rebuilding their mindsAug 19, 2025 · #llm
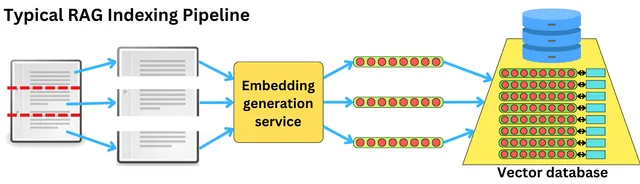 RAG: Giving LLMs an External BrainFrom keyword search to semantic retrieval, the journey to grounding models in realityAug 12, 2025 · #llm
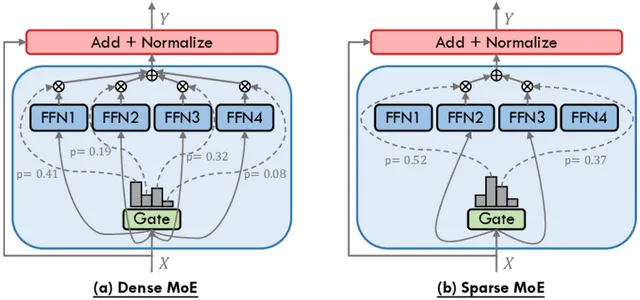 How MoE Powers Modern LLMsInside the Architecture That Trains Billion-Scale Models Without Breaking the BankAug 6, 2025 · #llm
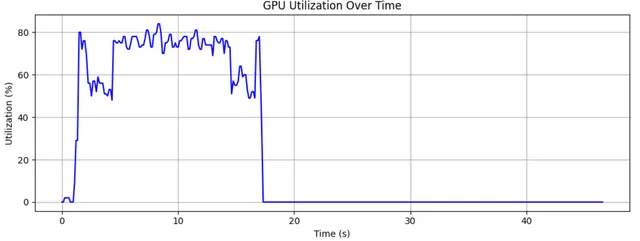 Continuous Batching: The Secret Sauce of High-Throughput LLM InferenceWhy batching in real-time matters, and how vLLM uses it to maximize GPU utilization.Jul 29, 2025 · #llm